AI agents stumble over data, not models. What this means for regulated sectors
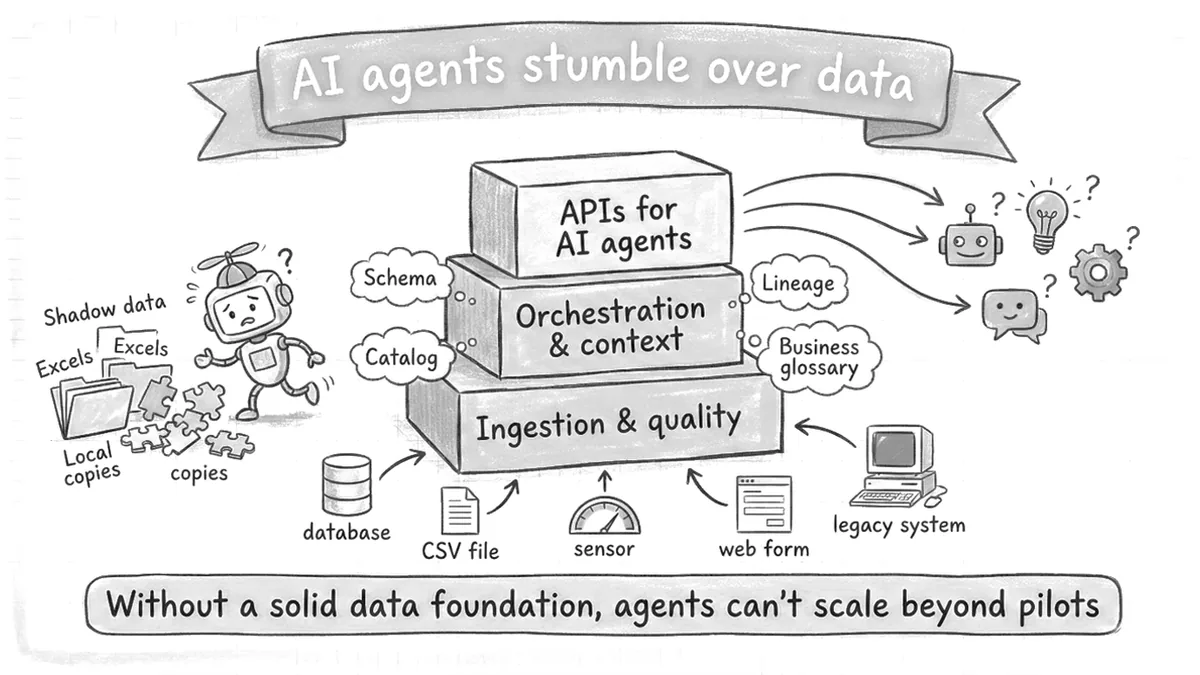
Nearly two-thirds of companies are experimenting with AI agents today, but less than one-tenth are scaling them to a level where they deliver measurable business value. In conversations with implementation teams — in banking, insurance, government, and energy — the culprit is almost always the same. It’s not the model. It’s not the agent framework. It’s the data foundation: silos, inconsistent definitions, porous quality control, governance that exists in policy but not in the system.
In the era of “gen AI + chat,” this foundation could still be hidden. A human sat between the model and the decision: they tweaked the prompt, filtered the output, ignored the hallucination. In the era of agents — that is, entities that access systems on their own, invoke tools, write to the database, and communicate with one another — that buffer is gone. And if the data is scattered, the agent will:
- make different decisions depending on which silo it happened to be reading from,
- lose context across channels (the same customer has three different “truths” across three systems),
- propagate errors through the workflow chain faster than a human can spot them.
At some point, it becomes impossible to “fix this manually.” The foundation must be improved — otherwise, every subsequent agent will exacerbate the problem rather than solve it.
Data foundation for AI agents
The data foundation as the operational core of the agent’s knowledge
Agent AI is not just a “model plus some glue code.” It is a nervous system built from data to which the agent has continuous, operational access. For such a system to work, several conditions must be met simultaneously:
- the data architecture supports autonomy and real-time decisions — not just delayed reporting,
- the data layers are modular and semantically consistent — the agent sees a single view of the world, regardless of which system it reads from,
- governance is embedded in the data flow itself, rather than added as an afterthought — because no one can manually evaluate every decision when there are a thousand agents, not just one.
In the CDF (Cognitive Deployment Framework) methodology, which I am developing as an approach to deploying AI in regulated sectors, I refer to this element as the agent’s operational knowledge core. Functionally, it consists of several layers that must communicate with one another: an operational memory linking a vector store, a domain knowledge graph, and a dialogue context with full provenance; a semantic layer (ontologies, definitions, relations); a retrieval pipeline where every response can be retroactively justified; and a gateway controlling the agent’s access to data and tools. And this is exactly the set of layers I’m assembling in my own production stack.
In regulated sectors, this isn’t “architecture” — it’s compliance
At this point, it’s important to mention something that standard industry publications rarely discuss, yet is absolutely critical for anyone deploying agents in a bank, insurance company, government agency, hospital, or critical infrastructure.
The data foundation for agents in the regulated sector is not solely an architectural decision. It is a compliance element. Four EU regulations that have just come into force or are about to come into force redefine the requirements for this layer:
- DORA (Digital Operational Resilience Act) requires operational reproducibility and incident reporting in financial institutions. In practice, this means that every agent decision must be retrospectively reproducible: what data was used, in which version, from which source, and with what level of certainty.
- The EU AI Act for high-risk systems (credit scoring, HR, critical infrastructure, administration) requires auditing, logging, and human oversight. This means the data foundation must retain the full provenance of every record that an agent consumes.
- NIS2 requires strict access control and the ability to respond to incidents in critical and key entities. This means the agent’s access to data must be under strict RBAC control, with logging of every read operation and escalation of violations.
- ISO/IEC 42001 (AI management system) requires documented processes for managing the lifecycle of AI systems, including their input and output data.
The combination of these four requirements means one thing: agent governance in the regulated sector cannot be built as a layer added on top of the data platform. It must be built into the workflow itself. In my practice, I implement this as a multi-level sovereignty gateway operating in fail-closed mode: an agent will not gain access to data for which it lacks permissions, even if a prompt attempts to force it; every access is logged; personal data is detected and masked before it leaves the retrieval layer, in accordance with industry standards for PII detection.
This is the part that no universal agent framework provides out of the box — it must be designed for the specific sector, regulations, and actual auditability requirements. And this is the moment when the data foundation ceases to be a conversation with the data engineering team and becomes a conversation with the CISO, compliance officer, and external auditor.
Seven characteristics of a foundation that can actually withstand agents
A good operational knowledge core — whatever we choose to call it — must have seven characteristics. These are not fads. They are things whose absence invariably resurfaces as a problem during production.
- Ingestion as a product. Every type of data — batch, real-time, structured, unstructured — has a repeatable, versioned, monitored ingestion path. There are no “ad hoc imports” that work, but no one knows why.
- Meaning, not just data. Shared definitions, dictionaries, semantics, domain ontology. An agent must know that a “customer” in CRM is the same entity as a “counterparty” in the payment system. Without this layer, every agent reinvents the wheel — and each does so differently.
- A single foundation for analytics and AI. Instead of building separate data pipelines “for reports” and “for models,” data is generated once and used everywhere. This is cheaper, but above all, more consistent — because the agent and the dashboard see the same truth.
- Trust built into the platform. Security, access control, privacy, data classification — automated, not manual for every project. In regulated sectors, this is a prerequisite for passing an audit.
- Stable interfaces to models and data. Clear APIs, access points, and contracts. Teams building agents shouldn’t have to “tread new paths” for integration every time.
- Visibility and measurability. Continuous metrics for data quality, model performance, inference cost, latency, and errors. Without this, the foundation degrades imperceptibly — until the day an agent makes a decision based on data that no one maintains anymore.
- A controlled agent execution layer. A shared execution environment that coordinates agents, enforces organizational policies, and serves as a gateway to data and models. Technical details may vary between implementations — what matters is the principle itself: agents never run “loose.”
Without these seven characteristics, any major agent-based project will sooner or later hit a wall — just in different places.
Two archetypes of agent workflows and their data requirements
In practice, I see two dominant patterns.
Single-agent — a single agent that sequentially uses multiple tools and data sources to execute an end-to-end process. Here, the greatest risk is inconsistent decisions resulting from fragmented data — the agent “sees” different versions of the truth in different systems and is unaware of it.
Multi-agent — a group of specialized agents that collaborate by sharing context through a common knowledge graph and precisely controlled access to data. Here, the risk is of a different nature: loss of coordination and cascading errors between agents if there is no shared semantics and strict access rules. From my implementations, it’s clear that the transition from single-agent to multi-agent is the moment when organizations most often hit the wall of the data foundation — a single agent forgave a lot; many agents forgive nothing.
In both cases, the solution is the same: a consistent semantic core and strictly enforced access rules. The only difference is the point at which the organization discovers this.
Before I get into specifics, there is one misconception worth dispelling right away. The seven characteristics I listed above do not mean you have to organize all the data in the organization before launching your first agent. Quite the opposite. The strategy of “let’s clean up the entire company first, then let’s bring in AI” is a path to paralysis — the same one that has stalled most Master Data Management and Data Lake initiatives over the past two decades. The foundation’s characteristics are built incrementally, within the specific workflow where you launch your first pilot. This workflow becomes a training ground for the entire platform. Only subsequent workflows expand the scope. Those who wait for a “ready-made foundation” will never get started. Those who start with a specific process with a measurable business stake build the foundation along the way — and do so more cheaply, faster, and with a greater chance that the solution will survive its first year.
Four steps to prepare data for agents
1. Choose workflows that are truly worth “agentizing”
Instead of “a little bit of everything,” it’s better to start with two or three end-to-end processes where greater autonomy will make a tangible difference in the business (underwriting, customer service, knowledge management, compliance monitoring). Every pilot project must have clear metrics and immediately consider the reusability of components — we’re not building a toy.
2. Modernize the foundation layers evolutionarily, not revolutionarily
It’s not about throwing everything out. It’s about strengthening key layers: sources, platforms, semantics, data products, and the consumption layer. In the regulated sector, a sovereignty gateway and a provenance layer are added to this — this isn’t an option, but a prerequisite for entry.
3. Shift from “occasional cleaning” to continuous data quality
A one-time “table cleanup before a project” isn’t enough. You need continuous quality monitoring, automated validations, anomaly detection, and data enrichment using AI models themselves. As part of CDF, I’m developing a multi-layered anti-hallucination defense system, where each layer has a different task, but together they form a rigorous data quality control regime that leaves nothing out. Data generated by the agents themselves must also be brought up to the same standard — it cannot be “dark matter” within the organization.
4. Build an operational agent management model
This is no longer an IT project — it’s a change in how we work. Written rules are needed (what an agent can do, what data it has access to, when human consent is required), automatic enforcement of these rules within the system, specialized guardrail agents to monitor the results of other agents, and a full agent lifecycle: identity assignment, login, monitoring, and decommissioning. In my practice, this model is codified in a contract I call the AI-Operating & Working Agreement — a federated agreement between the central team (platform, policies, oversight) and the business domains responsible for the agents’ day-to-day operations within their workflows.
Why this is a conversation worth having now
The companies that will succeed in the era of agent-based AI will not be those with the “biggest model.” They will be the ones that:
- consistently agentize successive workflows on a strong data foundation,
- have an architecture that allows agents to work on a shared view of reality,
- treat data quality, governance, and sovereignty as core capabilities, not just an afterthought to the project.
In regulated sectors, there is an additional dimension: the compliance layer ceases to be a burden and becomes a moat. Whoever can build a foundation that simultaneously complies with DORA, the EU AI Act, and NIS2 and supports agents in near real-time has an advantage that cannot be quickly replicated.
A micro-pattern from practice
Every document in the company repository — PDF, Word, email, report — can have an automatically generated “summary box”: three key points, the most important figures, a confidence level, and sources. Such a summary, created locally by a smaller model in the data enrichment layer, drastically increases the effectiveness of agents in the consumption layer — because the agent retrieving the document receives its essence as the first context before even beginning to read the details. The reduction of contextual chaos occurs before retrieval, not after. This is one of those micro-patterns whose absence in the data architecture isn’t visible in a demo, but becomes dramatic when there are a thousand agents instead of just one.
This series breaks down the transformation of AI in regulated sectors into seven layers:
- Physical infrastructure — AI devours electricity and fiber optics
- Legacy modernization — Legacy systems won’t die on their own
- Data foundation — AI agents stumble over data ← you’re reading this now
- Sovereignty: Diagnosis — You have data sovereignty, but you don’t have sovereign AI
- Sovereignty: practice — Sovereign AI in practice
- Human–system interface — From chatbot to collaborator
- Trust and leadership — Trust as the currency of AI scaling
The entire series is a record of what I’ve learned from working in regulated sectors — decisions that had to be made faster than caution allowed, mistakes that taught me more than successes, intuition honed in conversations with no script, and the will to build something that doesn’t yet exist.